Learn about how to work with ETL processes in Exasol.
What is ETL?
Loading data into a database in most cases means importing data from several data sources into a single target database. The data sources can be other database systems or flat files in cloud storage or on local or remote servers. The process usually begins with an initial full load, followed by periodic incremental loading of data to keep the data warehouse updated.
An ETL process divides the transfer of data from the source into the target system into three stages:
- Extract: Read data from the source system
- Transform: Modify data, convert data types, eliminate duplicates, aggregation operations, etc.
- Load: Write data to the target system
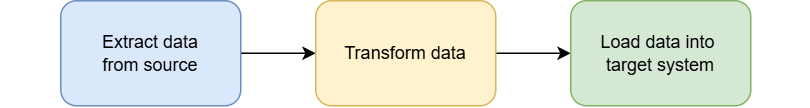
In Exasol you can use SQL statements in the database instead of external ETL tools to load data and perform complex data transformation such as data modifications, aggregation, or schema manipulations.
ELT (extract, load, transform)
In an ELT process, the transformation phase is performed after the extract and load phases. Because an ELT process exploits the high performance of a parallel cluster for complex operations, we recommend using ELT instead of ETL in Exasol whenever possible.
An ELT process involves extracting data from sources and loading it into a staging area in the database, then transforming the data using SQL (adjusting formats, checking primary keys and foreign keys, checking data quality, normalizing data), and finally integrating data into the target schema.
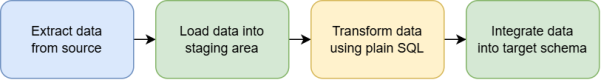
The staging area is usually a schema within the database that buffers the data for the transformation. The transformed data is then integrated into the target schema of the same database instance. There are several advantages of using a staging area:
- Because the transformation is done within the database, the full cluster performance is utilized.
- Integration of data from the staging area into the target schema is fast and uncomplicated.
- There is no contamination of data in the target schema with the temporary staging data.
Using IMPORT and EXPORT
Exasol includes a native bulk loader (EXALoader), eliminating the need for an external bulk loading tool. The native bulk loader increases performance by leveraging the parallel cluster, and simplifies the ETL/ELT process by allowing you to use the SQL statements IMPORT and EXPORT instead of external client tools and platforms that have to be installed and maintained.
You can use the IMPORT statement to import CSV and FBV files directly from local storage, from FTP/FTPS/SFTP/HTTP/HTTPS servers, from cloud services such as Amazon S3, Azure Blob Storage, and Google Cloud Storage, and from Hadoop.
Exasol 2025.1 and later also supports loading data from Parquet files that are stored locally, on remote file servers, or on cloud services. Which data sources are supported when importing Parquet files varies depending on which Exasol version you are using.
-
To learn more about how to use SQL statements for ETL, see Load data using IMPORT.
-
For more details about Parquet import options, see Importing Parquet files.
Exasol Cloud Storage Extension
Exasol Cloud Storage Extension provides user defined functions (UDFs) that enable you to easily transfer formatted data in various formats between Exasol and a large number of different cloud storage systems such as Amazon S3, Azure Blob Storage, Azure Data Lake, and Google Cloud Storage.
To learn more about how to use the extension, see Load data using Exasol Cloud Storage Extension.
Scripting complex ETL/ELT jobs
IMPORT statements are often part of a complex logic to update data in a data warehouse. For example, deleting old data or merging new and changed data, or even more complex processes such as cleaning the data. To create flexible ETL processes it is often necessary to monitor the exceptions and/or run different execution branches depending on certain conditions.
To handle complex ETL processes we recommend that you use scripting. Exasol’s scripting capabilities allow you to execute multiple SQL statements in a single script, to use exceptions handling, and to process smaller accounts of data directly in the programming language.
If standard interfaces such as files, JDBC sources, or native Oracle and Exasol connections are not sufficient for your ETL scope, you can develop your own custom ETL processes in Exasol with user defined functions (UDFs).
-
To learn how you can use UDFs for ETL processes, see Using UDFs for ETL.
-
To learn more about the scripting capabilities of Exasol, see Scripting.
Using virtual schemas for ETL/ELT
Virtual schemas is an abstraction layer that makes external data sources accessible in Exasol through SQL commands. The contents of the external data sources are mapped to virtual tables that can be queried as any regular Exasol table.
You can use virtual schemas to implement a loading process. Once a virtual schema is defined and the tables of the external data source are visible, an ETL job can materialize these tables using CREATE TABLE materialized_schema.my_table AS SELECT * FROM virtual_schema.my_table statement. You can run complex transformation directly in the subselect.
If you do not want to materialize all the tables, you can create a mix of views directly to the virtual tables and materialize once, then decide which table should be permanently stored in Exasol to get optimum performance.
To learn more about how to use virtual schemas for ETL processes, see Virtual schemas.
